
Understanding and addressing machine learning bias
What is machine learning bias and why does it matter?
Machine learning bias is when an algorithm produces unfair results because it learned from flawed or skewed data.
- It often starts in the training data, the model design, or how data is collected.
- It can lead to unfair treatment of certain groups and even discrimination.
- You can reduce it with clear standards, diverse data, and regular checks.
Machine learning algorithms can study huge amounts of data and make sharp decisions. However, one big concern stands out in this field: machine learning bias. These systems can perform incredible feats. Still, they are not free from bias that can shape their output and deepen social gaps. So this article looks at the impact, the causes, and the best ways to prevent and reduce bias in machine learning systems.
What is machine learning bias?
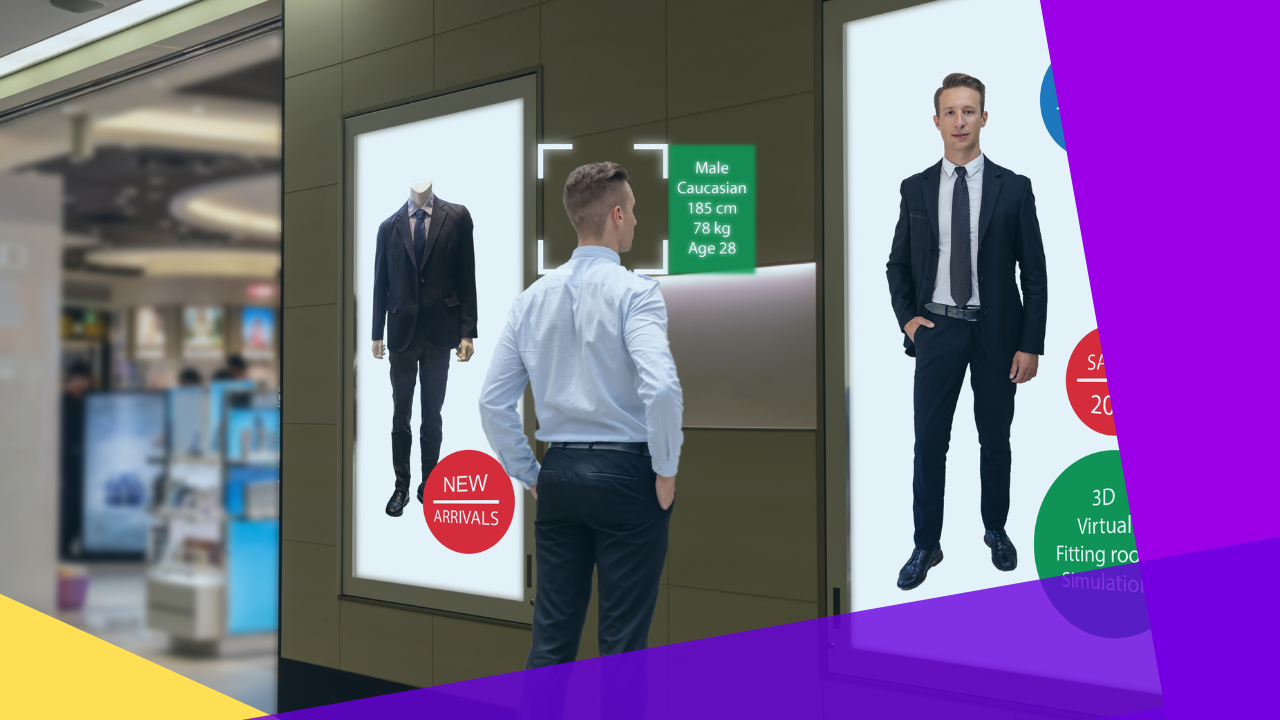
Machine learning bias means algorithms are not truly objective. Because they learn from data, they can pick up the biases of the people behind that data. As a result, a data set used to train a model may carry human bias that passes straight to the algorithm.
For example, a model may learn from past job applications that a woman is less likely to be hired than a man. So the bias in old hiring choices lives on in the system. In turn, machine learning bias can lead to unfair treatment of some groups or open discrimination. This risk grows as more teams adopt AI recruitment tools without a bias check.
Types of machine learning bias
A machine learning system can show bias in many ways. Below are the most common ones.
Algorithm bias
Algorithms face a “garbage in, garbage out” problem. So if you feed them biased data, they return biased results. Algorithm bias also comes from the limits of a model and its failure to capture every part of a problem. For example, you might train a model to sort images using photos from only one country. As a result, it will do poorly on pictures from other places, since it misses their cultural context. This bias is not always on purpose. Often, the builders simply do not weigh how certain data types affect the model.
Sampling bias
Sampling bias happens when a sample leaves some groups underrepresented. It can also appear when there are non-random gaps between the groups studied. For example, in medical trials, people who live near a hospital may be more likely to get treatment. So the sample tilts toward them. It can also occur when certain people are more likely to answer a survey. In addition, gaps between those who join and those who skip a study can skew results.
Confirmation bias
This bias occurs when a model trains on biased input and then uses that same data to predict future events. As a result, the machine repeats what already fits the user’s beliefs instead of offering fresh views. So this is a real concern, because it can push algorithms to learn from bad data and make weak predictions.
Measurement bias
Measurement bias comes from a flawed measuring tool. As a result, it can lead to wrong estimates, poor decisions, and false conclusions. In machine learning, this bias is common, because training data is often not accurate enough. So bad data collection can cause several problems, including:
- Overfitting the model – If you use too much old data, the model may learn patterns from the past that do not fit the future. So it fails when it meets new data.
- Underfitting the model – If you do not have enough data, the model cannot account for every factor that shapes your target, such as profit.
Exclusion bias
Exclusion bias happens when an algorithm marks a data point as irrelevant, even though it matters. As a result, the model is less accurate than it could be. It can occur in two ways:
- An algorithm drops some data points because they miss certain criteria.
- An algorithm blocks some groups from its services based on traits like race, gender, or age.
Recall bias
Recall bias is a common type of machine learning bias. It occurs when results skew because the model can reach only certain data. In other words, the model cannot hold enough detail about a case to make an accurate call.
Prejudicial bias
Prejudicial bias reflects the pull of human prejudice on an algorithm’s choices. These biases can be conscious or not. Often, they come from the coder’s beliefs or simply mirror society’s norms. So this bias shows up when a model learns from human data that holds racial, gender, or other prejudice.
How to prevent machine learning bias
It is never too late to guide machine learning, even with today’s limited AI. Below are some steps that build a base for preventing bias. Many teams also lean on AI and ML solutions from vetted partners to add this rigor.
Set standards and guidelines
A model only works as well as the data behind it. Data can be biased in many ways. So you can curb this with clear standards for how you gather data. First, write a code of conduct for your organization. It should set rules for how staff behave when they collect data. A strong data collection strategy makes these rules easier to follow. Next, form an ethics review board to oversee every machine learning project. In addition, the board should include people from HR, sales, marketing, and engineering.
Recognize potential sources of bias
Here are some ways to spot sources of machine learning bias:
- Understand how your data is collected and processed.
- Look for patterns in your training data.
- Use a diverse set of samples in your training data.
- Test your model against different sets of data.
The biggest source is the data itself. So if you train on biased data, the model will be biased too. Another source is the model. When you train it, you make quiet assumptions about how the world works. As a result, those assumptions can create bias.
Evaluate models for early indicators
Before you deploy a system, test it for any bias first. For example, you might check whether the model sorts your customer base well. So use test data that mirrors that base as closely as you can. If the test data and the real thing do not match, dig deeper before you go live. A clear view of the machine learning development life cycle helps you catch these gaps early.
Monitor and review applications regularly
Machine learning and AI at this scale are still fairly new in business. So monitoring should be a regular task. If the AI does not work as planned, find out why before it hurts your customers or staff. As a result, frequent reviews help you catch problems while they are still small.
Future directions and challenges for machine learning bias
Future directions and challenges for machine learning bias include the following.
Fairness-aware machine learning
There is a growing need for fairness-aware machine learning techniques that address and reduce bias head-on. So researchers are testing new methods. For example, these include causal reasoning, counterfactual fairness, and adversarial debiasing.
Algorithmic transparency and explainability
Clear, readable algorithms are key to spotting and fixing bias. As a result, teams now build methods that explain how AI systems reach a decision. So stakeholders can find and correct bias more easily.
Intersectionality and multiple biases
Bias rarely acts alone. Multiple biases can mix and stack, which creates complex forms of discrimination. So future research should account for this overlap. In addition, it should weigh the combined impact of several biases at once.
Data privacy and bias
Protecting personal data now matters more than ever. As a result, teams face a balancing act between data privacy and the need for diverse, representative data. So finding the right balance remains a real challenge.
Ethical considerations and regulation
People increasingly see the ethical weight of machine learning bias. So there is fresh demand for ethical frameworks and clear guidelines. In addition, policymakers and regulators are drafting standards to ensure fairness, transparency, and accountability.
Bias in reinforcement learning
Reinforcement learning models learn through trial and error. Still, they too can pick up bias. So fixing bias in these systems is an emerging field. As a result, the focus is on methods that keep outcomes fair and unbiased.
Education and awareness
Raising awareness of machine learning bias is vital. So training programs and open debate help people question bias in AI. As teams scale up AI outsourcing, this shared knowledge matters even more. In addition, this work needs teamwork across researchers, industry, policymakers, and the public. By working together, we can build fair, unbiased, and responsible machine learning systems that serve diverse people.
Frequently asked questions about machine learning bias
What causes machine learning bias?
Bias usually starts in the training data. However, it can also come from the model design or from how data is collected. So a biased data set almost always leads to a biased result.
How can you detect machine learning bias?
You can test a model against diverse data sets and look for uneven results. In addition, you can review the training data for gaps. As a result, early testing helps you catch bias before you deploy the system.
Can machine learning bias be fully removed?
No system is perfectly free of bias. Still, you can reduce it a lot with clear standards, diverse data, and regular checks. So the goal is to manage and lower bias, not to claim it is gone.
Why is machine learning bias a business risk?
Biased models can make unfair calls in hiring, lending, or service. As a result, they can harm customers and damage trust. In turn, this can lead to legal and reputational costs.
Who should oversee machine learning fairness?
A cross-team ethics board works best. So it should include people from HR, engineering, marketing, and legal. In addition, this mix helps the group spot bias from many angles.






 Independent






